 |
Continuum C++ API
Unified runtime for token + tensor execution
|
|
Continuum C++ API
Unified runtime for token + tensor execution
|
#include <mlx_backend.hpp>
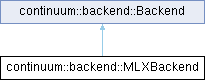
Public Member Functions | |
| BackendCapabilities | capabilities () const override |
| std::string | tensor_backend_type () const override |
| BackendRunResult | run_with_cache (const ir::Node &node, const std::vector< continuum::Value > &inputs, const std::optional< BackendState > &prefix_state, std::int32_t remaining_tokens) override |
 Public Member Functions inherited from continuum::backend::Backend | |
| virtual | ~Backend ()=default |
| virtual std::vector< std::uint8_t > | export_state (const BackendState &) const |
| virtual std::optional< BackendState > | import_state (const std::vector< std::uint8_t > &) |
Static Public Member Functions | |
| static std::string | runtime () |
| "mlx <version> (gpu|cpu)" when built against MLX, else "reference (built without MLX)". | |
Tensor backend behind the mlx tensor type (CONTINUUM_TENSOR_BACKEND=mlx).
Built with Apple's MLX (CONTINUUM_USE_MLX, on by default when the mlx package is installed on Apple silicon), every op runs as an mlx::core kernel: on the Metal GPU on Apple silicon (CONTINUUM_MLX_DEVICE=cpu to pin the CPU), on the CPU with Linux wheels. Built without MLX, the same ops fall back to portable C++ reference kernels. runtime() reports which is in use. Tensors are row-major float32 MlxTensorValues. Ops: identity / input / id, relu, softmax (attr 0 = dim, default -1), add (same shape), matmul (1D x 1D dot, or 2D x 2D). Tensor-only: no token path, no cache, no portable state. See the capability matrix in docs/design/abi.md.
|
overridevirtual |
Implements continuum::backend::Backend.
|
overridevirtual |
Implements continuum::backend::Backend.
|
static |
"mlx <version> (gpu|cpu)" when built against MLX, else "reference (built without MLX)".
|
inlineoverridevirtual |
Reimplemented from continuum::backend::Backend.
 1.9.8